 លំហសិក្សាកម្ពុជា
V1.0
លំហសិក្សាកម្ពុជា
V1.0
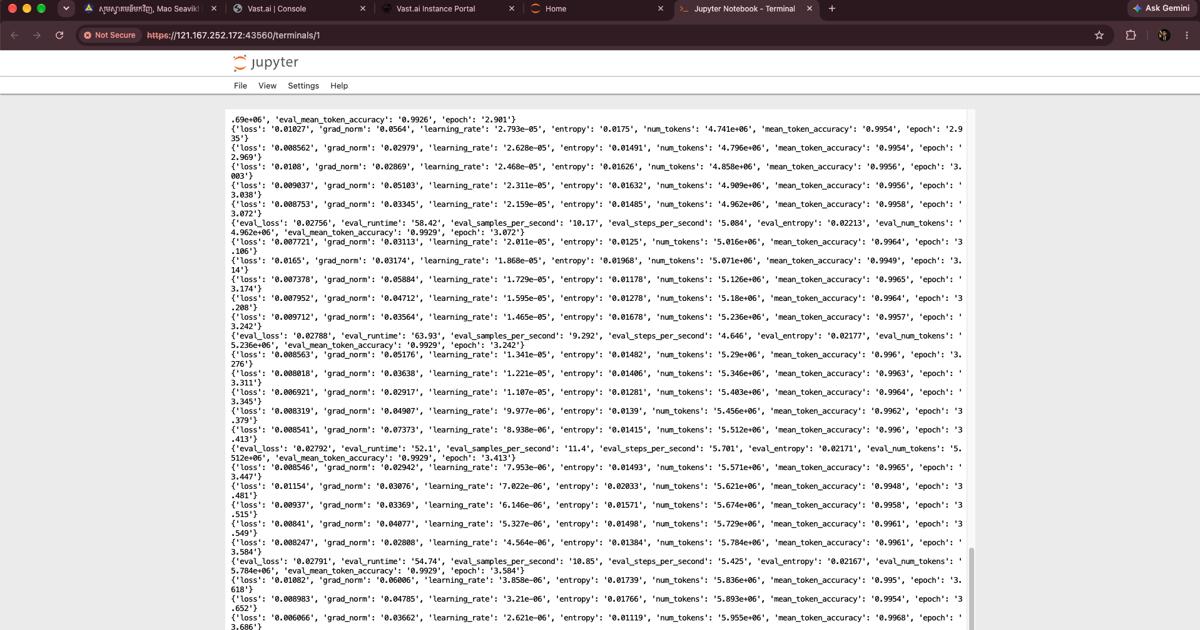
A quick look into real-time training metrics from our Jupyter instance, tracking convergence behavior, gradient norms, and token-level accuracy across recent epochs.
When monitoring a model training run, keeping an eye on the core metrics helps ensure the optimization process is stabilizing correctly. In our current session running inside Jupyter
Loss & Evaluation Loss: Observing a steady progression through the epochs
Gradient Norm (grad_norm): Tracking gradient magnitudes
Learning Rate Schedule: Utilizing dynamic learning rate adjustments
Token Accuracy (mean_token_accuracy): Maintaining high token-level precision
{

   "loss": "8.0115",
   "grad_norm": "0.8307",
   "learning_rate": "7.822e-06",
   "entropy": "8.0283",
   "epoch": "3.481"
}
Above: A sample snapshot of the active training log metrics

មតិយោបល់ 2